Laryngeal Imaging & Neurogenic Voice Disorders

We use AI and high-speed videoendoscopy during connected speech to develop objective measures of laryngeal function in individuals with neurogenic voice disorders, including laryngeal dystonia.
Read More
Neurogenic voice disorders arise from disruptions in the neural control of laryngeal muscles, profoundly affecting voice quality and communication. Our lab uses simultaneous laryngeal high-speed videoendoscopy (HSV) and acoustic recordings to capture vocal fold dynamics in both vocally normal individuals and patients during connected speech and sustained phonation. We develop automated deep learning and machine learning methods to extract glottal measures and quantify vocal fold motion and supraglottic laryngeal behavior. These tools enable large-scale, objective analysis of HSV datasets and support the development of imaging-based biomarkers that link vocal fold kinematics to the generated voice signal. The long-term goal of this work is to advance precision assessment of neurogenic voice disorders and to inform more accurate diagnosis and treatment planning.
Voice-Based Biomarkers of Health
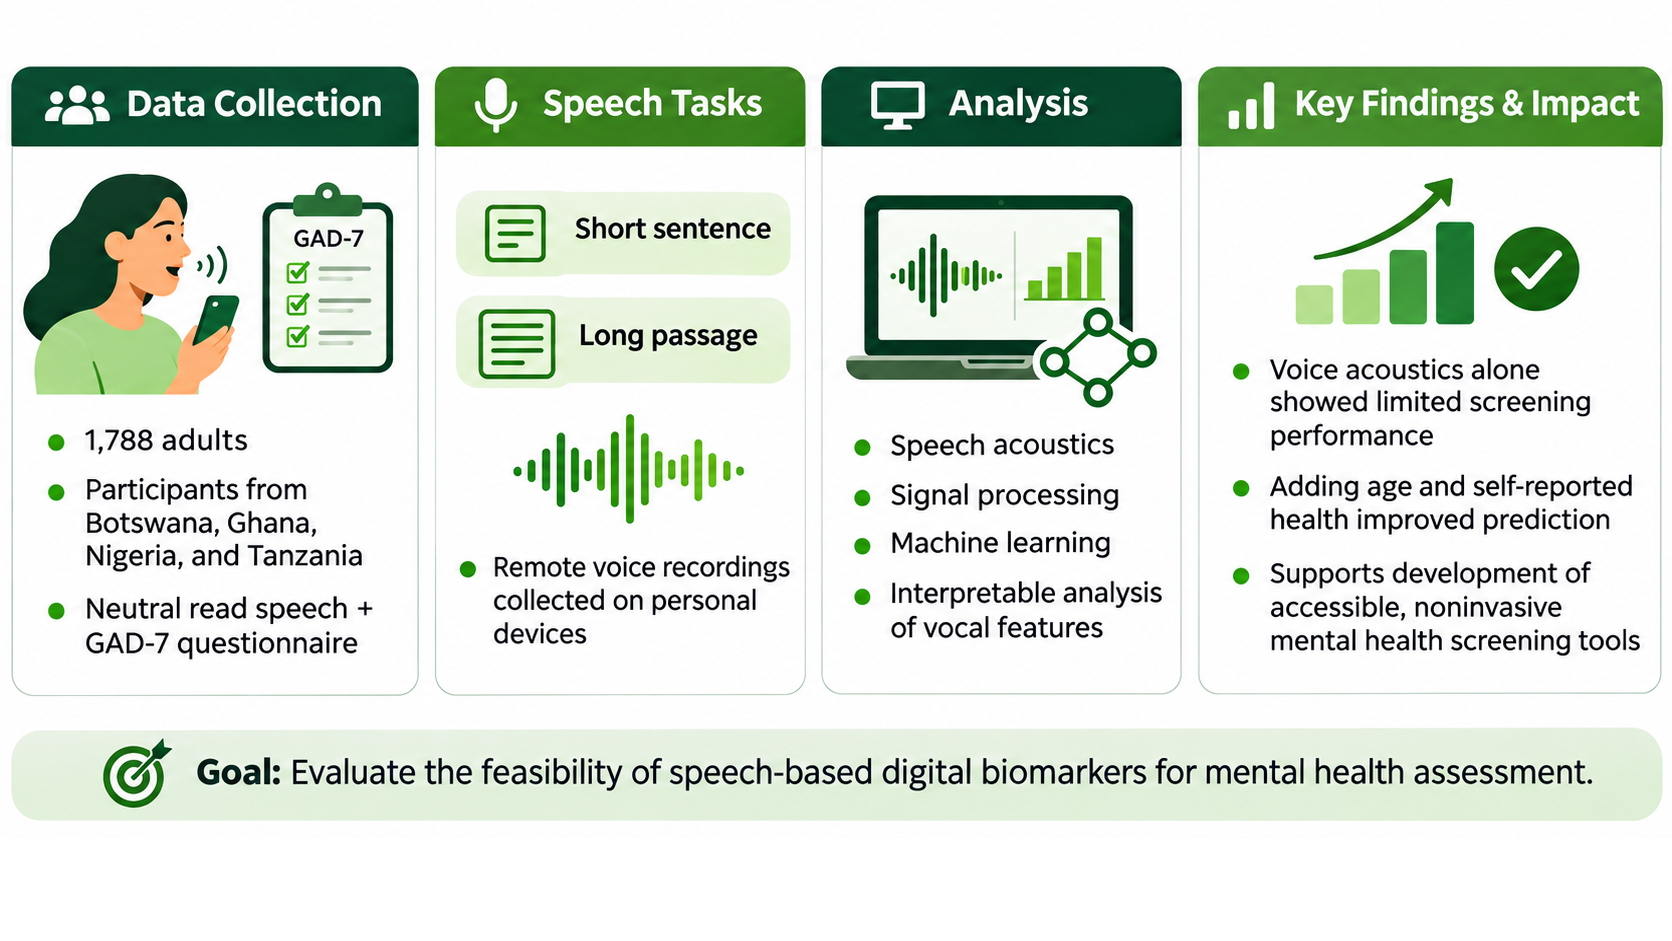
We investigate how rich voice data can serve as noninvasive biomarkers of health, with active projects in mental health assessment and laryngeal cancer detection.
Read More
The voice encodes rich physiological information about a speaker's health. Our lab develops AI-driven methods to extract clinically meaningful information from voice signals as a window into systemic and laryngeal health conditions. In the domain of mental health, we investigate acoustic and phonatory features as noninvasive markers of generalized anxiety disorders, drawing on large multi-country cohort data to build and validate predictive models. In the domain of laryngeal cancer, we are developing quantitative approaches that integrate voice acoustics and machine learning to study how laryngeal cancer and its treatment affect voice and laryngeal function, with the goal of enabling earlier detection and better monitoring of treatment outcomes. Together, these projects advance the use of voice as a scalable and accessible tool for health screening and evaluation.
Physics-Informed Modeling of Voice Production
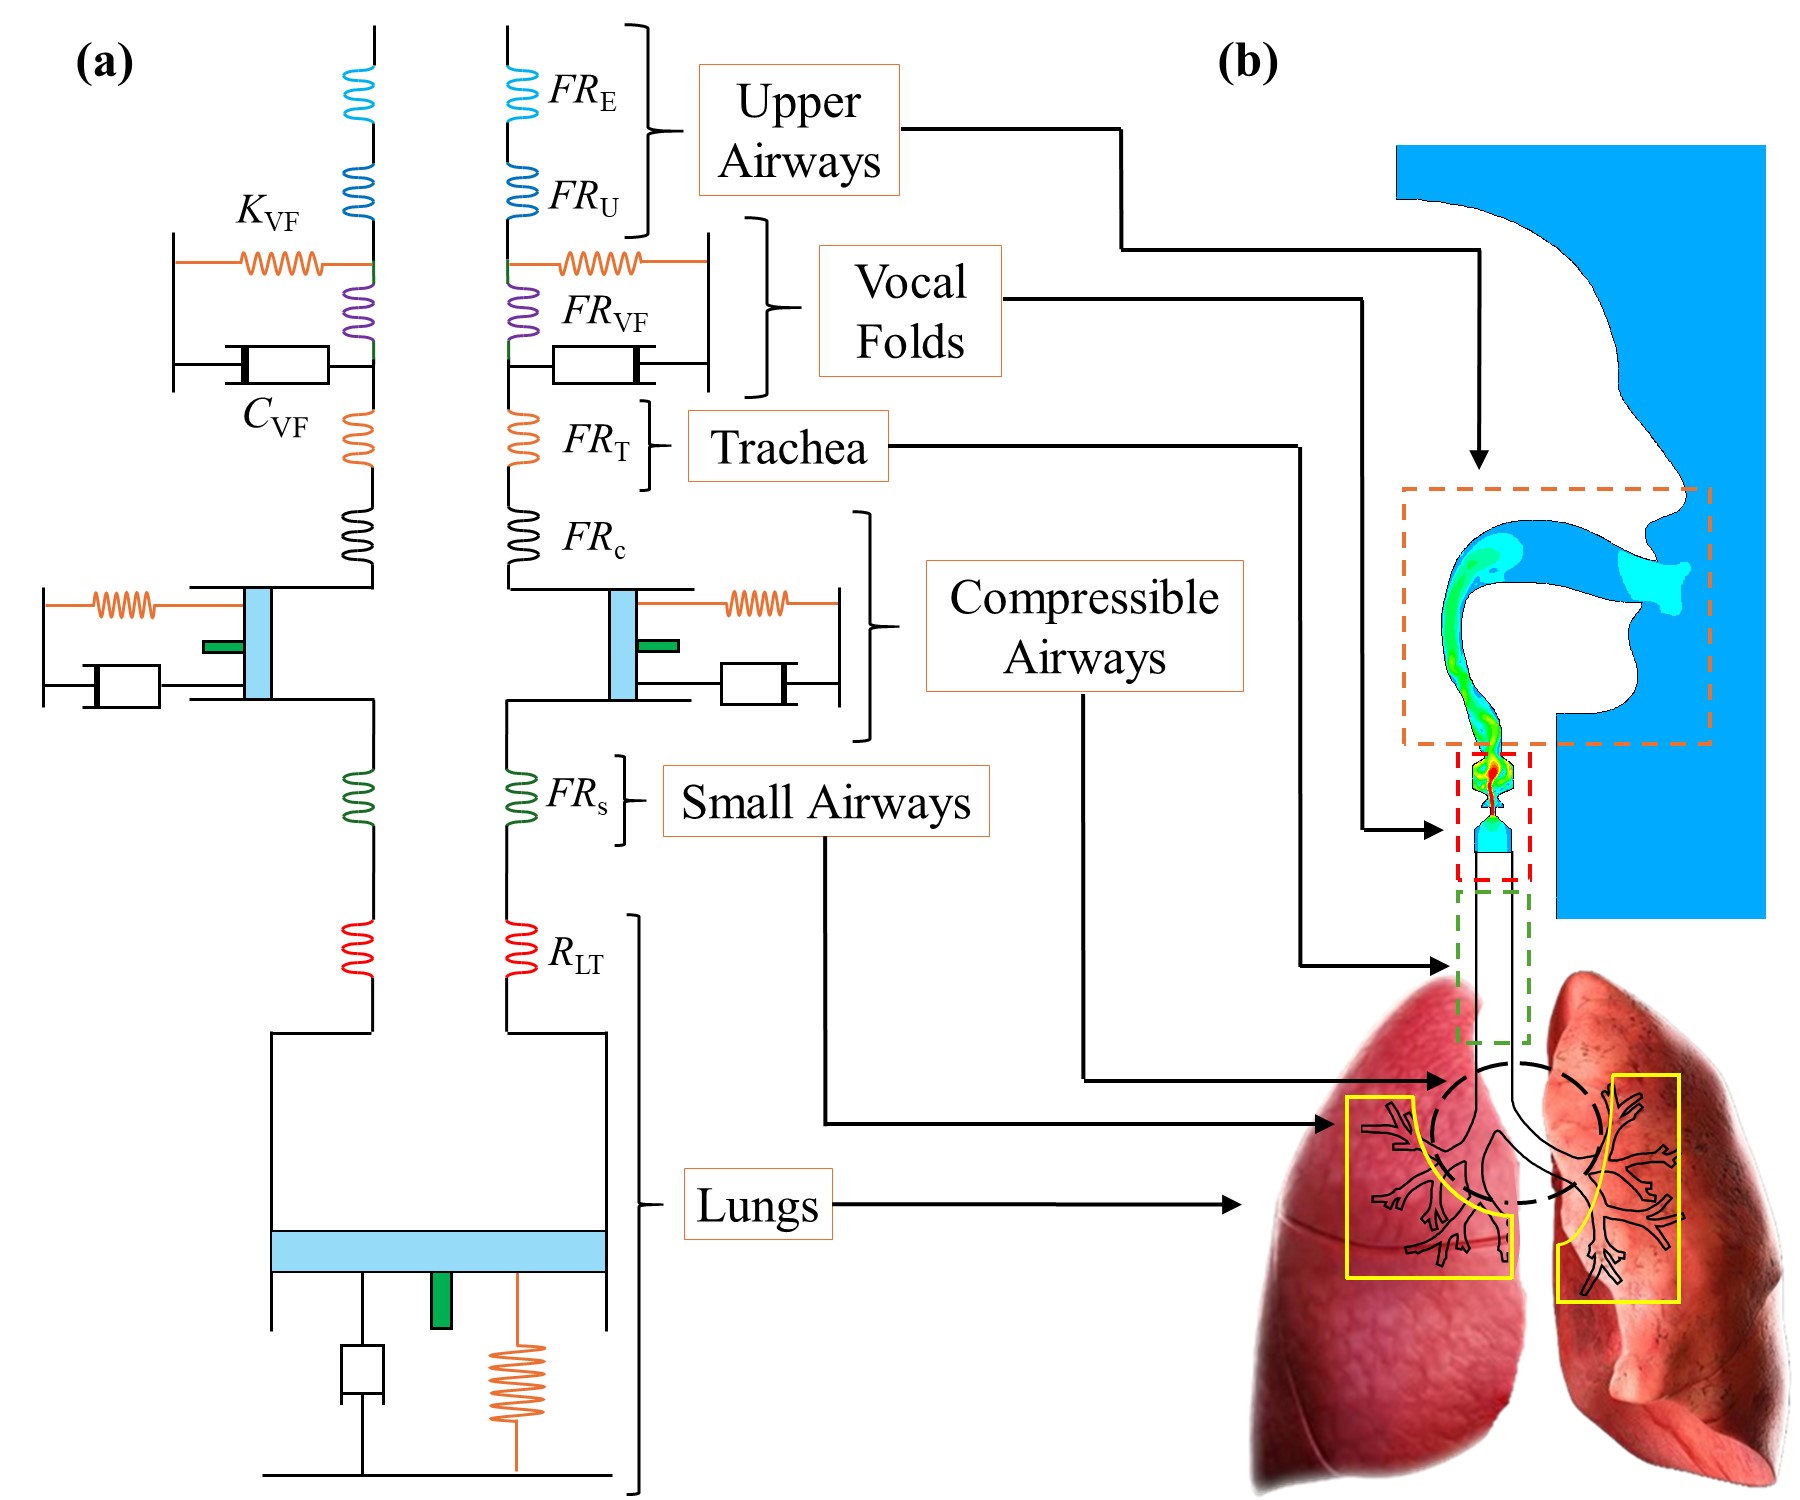
We develop holistic computational and data-driven models of voice production that include the respiratory, phonatory, and articulatory subsystems to investigate the physical mechanisms underlying normal phonation and voice disorders.
Read More
Understanding the physics of voice production requires bridging anatomy, fluid mechanics, and vocal fold biomechanics in ways that are difficult to observe directly. Our lab develops physics-based computational models to investigate how airflow travels from the lungs through the trachea, interacts with the vibrating vocal folds, and propagates through the upper airway during phonation. Physiological information obtained from high-speed videoendoscopy and magnetic resonance imaging is incorporated to develop subject-specific simulations of airflow, pressure, vocal fold motion, and aerodynamic forces. We also integrate Bayesian inference and machine learning with computational simulations to build data-driven, subject-specific models of voice production for both normophonic and structurally disordered voices. Reduced-order modeling further enables computationally efficient prediction of complex airflow dynamics. This work advances the fundamental understanding of normal voice production and establishes a computational foundation for investigating the physiological mechanisms underlying voice disorders.
Biomechanics of Auditory Sound Transmission
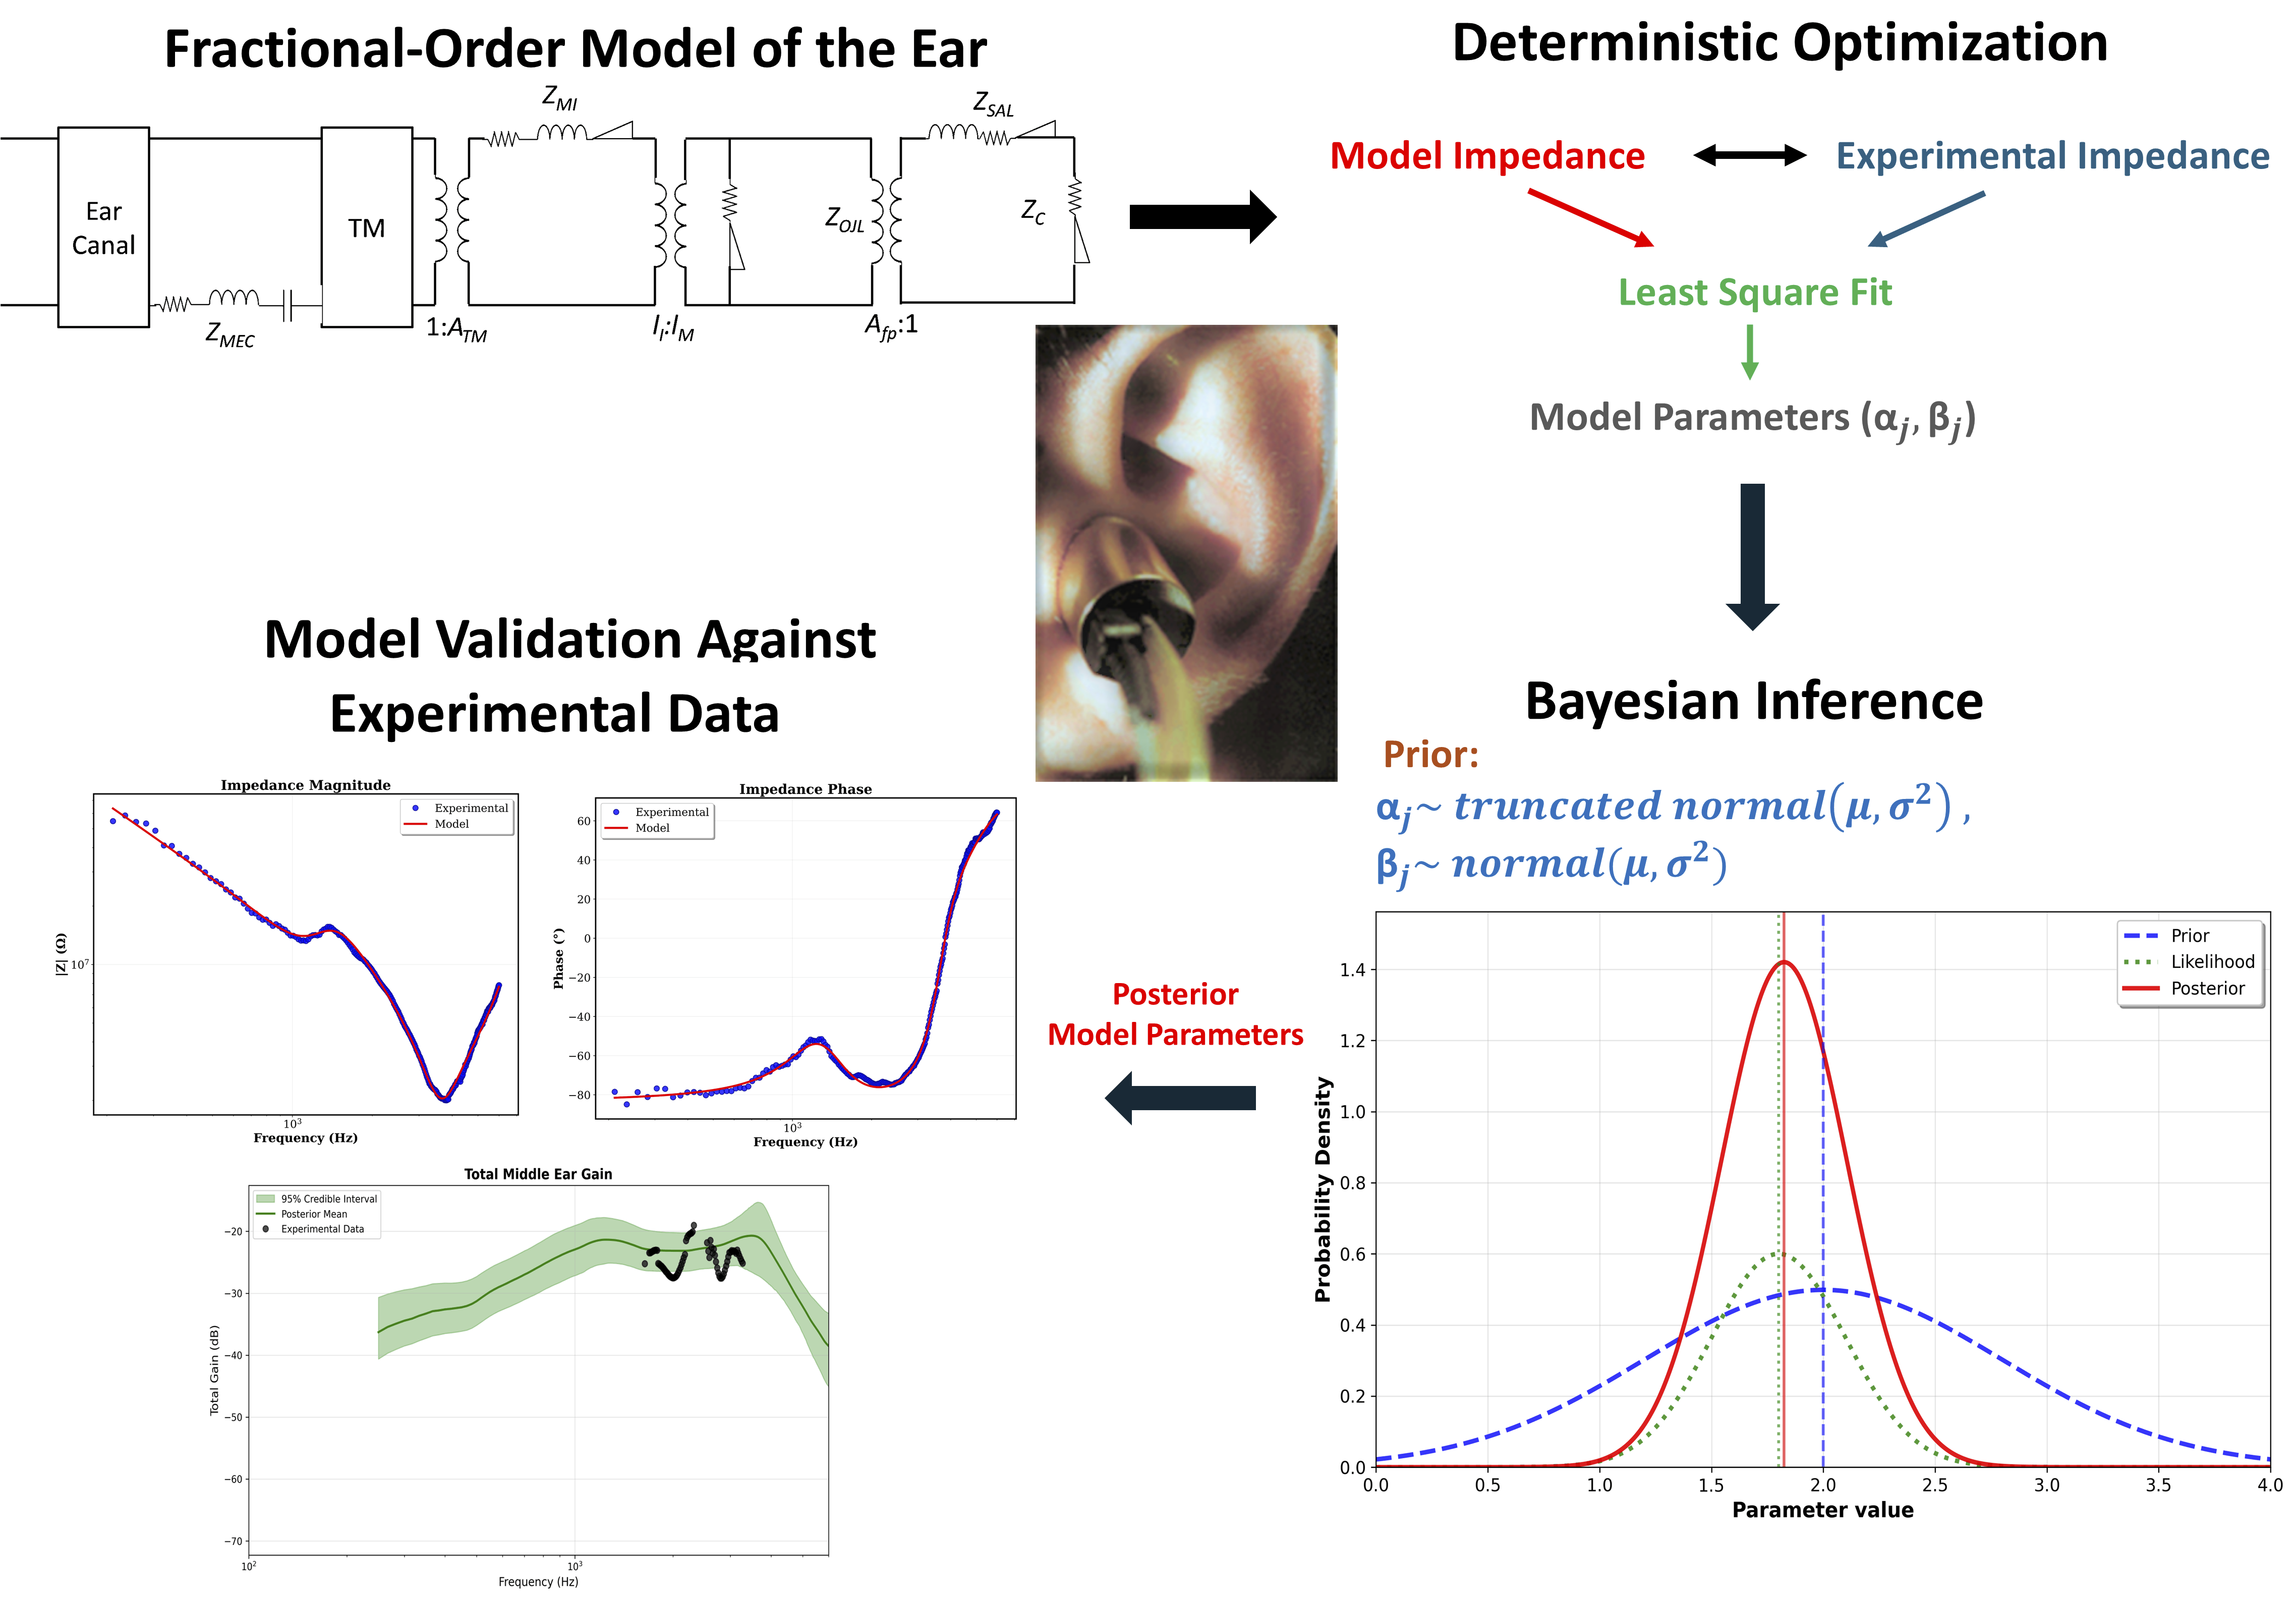
We study how acoustic signals travel through the human auditory system using mathematical and computational models, with the aim of understanding variability in perceptual voice assessment.
Read More
Perception of voice depends on the integrity and function of the listener's auditory system, yet the mechanical and physiological pathways through which sound energy is converted to neural signals remain incompletely understood. Our lab investigates the biomechanics of sound transmission through the auditory system using fractional-order mathematical models and computational simulations. These models capture the viscoelastic and history-dependent properties of ear tissues that classical models often overlook, allowing more accurate representation of how the tympanic membrane, ossicular chain, and cochlea process incoming sound. By modeling how individual differences in auditory mechanics shape sound perception, this work aims to illuminate a source of variability in how clinicians and listeners perceptually assess voice quality, ultimately contributing to more reliable and standardized approaches to voice evaluation.